

You published your website, your pages look great, but nobody’s finding you on Google. Before you blame your content or your keywords, there’s something you need to check first: the Google Search Console coverage report (now called the Page indexing report). This report tells you exactly which pages Google has indexed, which ones it hasn’t, and, most importantly, why certain pages aren’t showing up in search results at all.
For small business owners, this matters more than you might think. Every page that Google can’t index is a page that potential customers will never see. Whether you’re running a five-page brochure site or a full e-commerce store, indexing issues silently eat into your visibility and cost you traffic. At Avatar Website Design, we handle SEO optimization and ongoing maintenance for our clients’ websites, and the coverage report is one of the first tools we check when diagnosing search performance problems.
This guide walks you through everything you need to know, how to access the report, what each status means, and how to fix the most common indexing issues step by step. No prior technical experience required. By the end, you’ll know how to read this report with confidence and take action on the errors that are holding your site back.
What the Page indexing report is and why it matters
The Page indexing report (previously called the coverage report in Google Search Console) is a diagnostic tool that shows you exactly how Google has processed every URL it has found on your site. It breaks your pages into status groups so you can see which URLs are fully indexed, which carry warnings, which have errors, and which have been deliberately excluded. Think of it as Google handing you a detailed report card on your site’s crawlability, one that tells you not just what happened, but where in the process something went wrong.
Where it lives and what Google renamed it
Google renamed the coverage report to the Page indexing report as part of a broader redesign of Search Console that began rolling out in 2022. The core data stayed the same, but the updated interface adds more granular detail and groups URLs by the specific reason they were excluded or blocked. You can find it in the left sidebar of Search Console under Index > Page indexing.
If you’ve been searching for the old coverage report and can’t locate it, that’s the reason. The navigation and label changed, but the function is identical: it tells you whether Google can discover, crawl, and index your content, and it flags the exact issue when it can’t.
What data the report actually pulls
The report works by pulling data from Googlebot’s crawl activity and Google’s indexing pipeline. When Googlebot visits your site, it reads your pages, processes them, and sends that information back to Google’s servers. The Page indexing report reflects what happened at each stage of that process, not just whether a page made it into the index, but at exactly which point in the pipeline something went wrong.
A page can fail at several different points: Google might not be able to crawl it at all, it might crawl the page but decide not to index it, or it might index a different version of the page than the one you intended.
The report also pulls from all URLs Google has discovered, including ones you haven’t added to your sitemap. That means you might see pages you forgot about, old URLs that are still getting crawled after a redesign, or duplicate versions of pages that are splitting your indexing signals and confusing Google about which version to rank.
Why small business owners need to check it regularly
For a small business site, every indexed page is a potential entry point for a customer searching on Google. If your services page, your about page, or your location page isn’t indexed, those customers will never reach you through search, no matter how good your content is. The google search console coverage report hands you a concrete, actionable list of what’s missing and what’s broken, so you’re not left guessing why your traffic isn’t growing after you’ve put in the work.
Running through this report at least once a month keeps small problems from quietly growing into large ones. Indexing issues develop gradually, especially after a site update, a new plugin, or a theme change that accidentally altered your robots.txt or added noindex tags across multiple pages. Catching a problem when two or three pages are affected takes maybe an hour to fix. Discovering it three months later, after an entire section of your site has been blocked from Google, is a much heavier lift. Staying on top of this report is one of the lowest-effort, highest-impact habits you can build for your site’s long-term search health.
Step 1. Open the report and set the right view
Getting to the right place in Google Search Console takes less than a minute, but setting the view up correctly before you start reading the data will save you from misreading what you see. A quick configuration step here pays off every time you return to the report.
How to navigate to the Page indexing report
Start at Google Search Console and select the property that matches your website. If you have multiple properties set up (for example, both the www and non-www versions of your domain), make sure you pick the correct one. From the left sidebar, click Index, then click Page indexing. That’s the updated name for what the google search console coverage report used to be called.
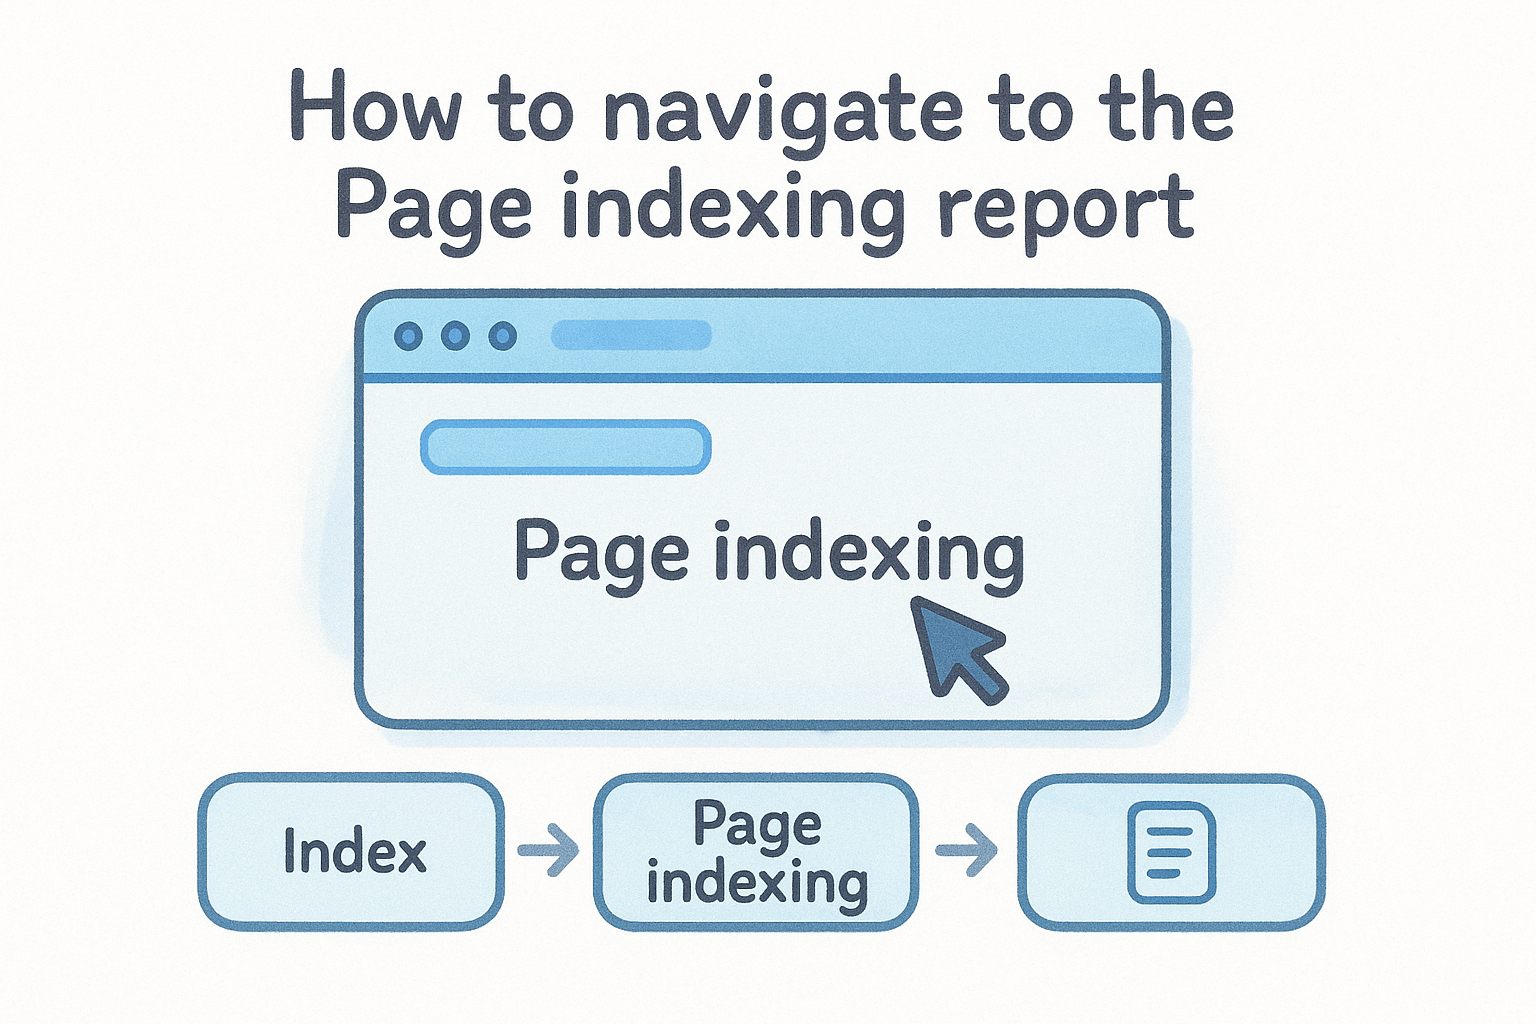
Follow these steps in order:
- Sign in to Google Search Console at search.google.com/search-console
- Select your website property from the top-left dropdown
- Click Index in the left navigation menu
- Click Page indexing from the expanded submenu
- Wait for the chart and status breakdown to fully load
If you land on a screen that says "Data not available," your property either hasn’t been verified yet or hasn’t accumulated enough crawl data for Google to display results.
Choosing the right date range and filters
Once the report loads, your first instinct might be to read the numbers at the top, but take a moment to adjust the date range first. The default view shows the last three months, which is a solid starting point for most small business sites. If you recently made changes to your site, such as updating your sitemap or fixing a robots.txt issue, narrow the date range to the last 30 days so you can isolate recent changes from older, unrelated data.
Your report also lets you filter by crawl type using the dropdown at the top of the chart. The two options are Googlebot Smartphone and Googlebot Desktop. For most small business websites, smartphone crawling is the one that matters most, because Google operates on a mobile-first indexing model, meaning it primarily uses the mobile version of your site to determine rankings. Confirm that the smartphone view is selected before you start diagnosing any issues.
Step 2. Read the four status groups correctly
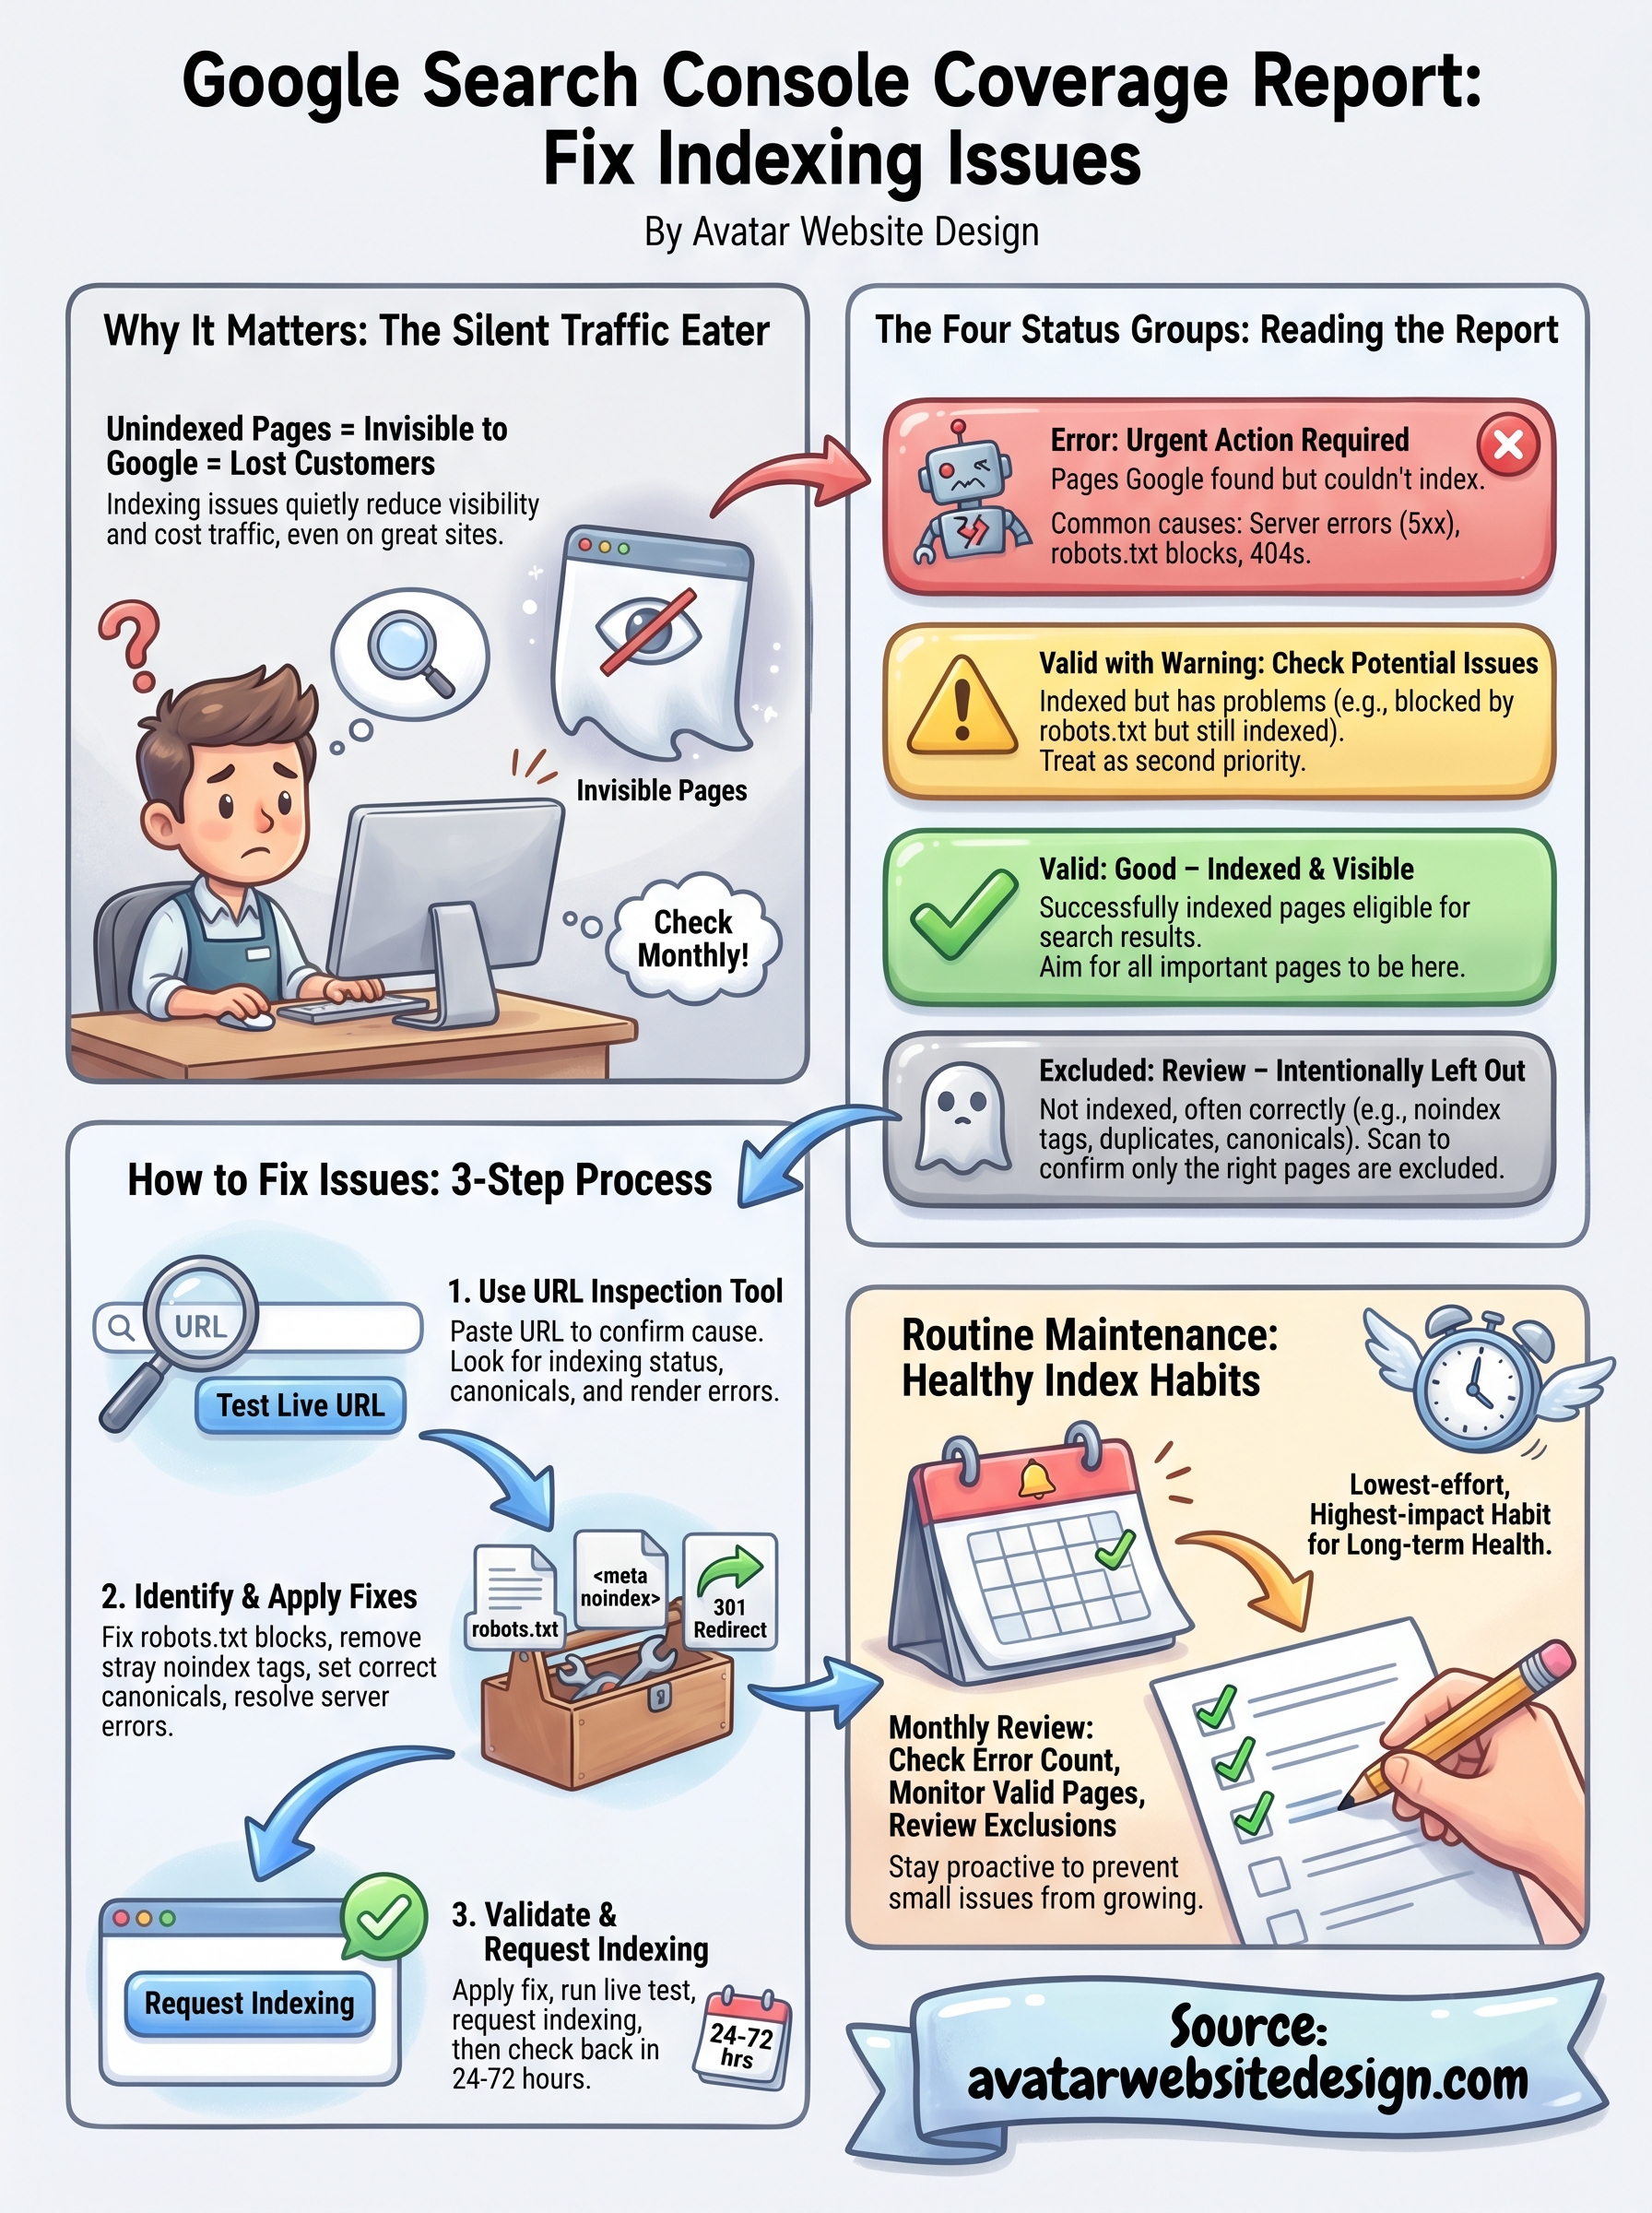
The Page indexing report organizes every URL Google has found on your site into four status groups: Error, Valid with Warning, Valid, and Excluded. Reading these groups in the right order, starting with Error and working down, gives you a clear picture of what needs your attention first and what you can safely set aside for later.
Error: pages Google could not index
Error is the most urgent group. These are pages that Google found but couldn’t successfully index because something in the crawling or processing pipeline broke down. Common error types include pages that returned a server error (5xx), pages blocked by a robots.txt rule that conflicts with your intent, and pages that returned a 404 status when Googlebot tried to visit. Click any error type in the list to see exactly which URLs triggered it, then click individual URLs to investigate the specific problem.
Valid with Warning: indexed but not clean
Pages in this group made it into Google’s index, but something about them signals a potential problem. The most common warning is "Indexed, though blocked by robots.txt," which means Google crawled and indexed the page even though your robots.txt file technically told it not to. This sounds minor, but it can push unexpected pages into search results when you didn’t intend them to appear there. Treat warnings as a second-priority fix, right after you work through all active errors.
Don’t skip the Valid with Warning group just because pages are technically indexed. A warning often points to a configuration conflict that will cause bigger problems over time.
Valid: the baseline you’re working toward
Valid pages are successfully indexed and eligible to appear in Google search results. This is where you want all your important pages to land. Use this group as your benchmark: compare the number of valid pages against the total number of pages your site should have indexed to spot gaps quickly. If your site has 20 core pages but only 14 show as valid, you have six pages to track down and fix.
Excluded: not indexed, but not always a problem
The Excluded group is the largest and most misread section of the google search console coverage report. Not every excluded page needs a fix. Pages you’ve intentionally marked with a noindex tag, pages blocked by robots.txt, and duplicates that Google has consolidated under a canonical URL will all appear here. Your job is to scan this list and confirm that only the right pages are excluded, not the ones you actually want customers to find through search.
Step 3. Use URL Inspection to confirm the cause
The Page indexing report tells you what happened, but it doesn’t always tell you exactly why. That’s where the URL Inspection tool comes in. Before you spend time changing files or rewriting code, run an inspection on any URL showing an error or a suspicious exclusion. This step gives you a direct look at what Google sees when it visits that specific page, so you’re fixing the actual problem rather than guessing.
How to run a URL inspection
You can access the URL Inspection tool from two places: by clicking any URL listed inside the google search console coverage report, or by pasting a URL directly into the search bar at the top of Search Console. Both routes take you to the same inspection screen. Follow these steps each time you need to investigate a specific page:
- Copy the exact URL from the affected page on your site
- Paste it into the search bar at the top of Google Search Console
- Press Enter and wait for the inspection to load
- Read the "Coverage" section in the results panel on the right
- Click "Test Live URL" to run a fresh crawl and compare it against the last indexed version
- Review the rendered screenshot to confirm what Googlebot actually sees when it visits your page
If the live test shows different results than the stored data, it means Google’s last crawl is out of date and a reindex request may resolve the issue without any further changes.
What to look for in the inspection results
Once the inspection loads, focus on three data points: the indexing status, the canonical URL Google selected, and any crawl or rendering errors. If the canonical Google chose doesn’t match the URL you inspected, that tells you Google has decided another version of the page is the primary one, which is a duplicate content problem you’ll need to address directly.
The rendered screenshot is equally important. If your page is blocking JavaScript, CSS, or other resources, the screenshot will show a broken or blank page, which explains why Google can’t properly read your content. A fully rendered screenshot should look nearly identical to what you see when you open the page in a standard browser. Anything significantly different signals a rendering problem that needs its own fix before your content can be indexed correctly.
Step 4. Fix issues that block crawling and indexing
Once URL Inspection confirms the cause of an error, you can move into fixing it. The most common crawling and indexing blockers fall into three categories: robots.txt rules that accidentally block important pages, server errors that prevent Googlebot from loading the page at all, and noindex tags that were placed on pages you actually want indexed. Each one has a direct, testable fix you can apply without needing a developer for most cases.
Fix accidental robots.txt blocks
Your robots.txt file controls which parts of your site Googlebot is allowed to crawl. A single misplaced rule can block an entire folder of pages. Open your robots.txt file by navigating to yourdomain.com/robots.txt in a browser. If you see a Disallow rule that covers a URL showing as blocked in the google search console coverage report, remove or narrow that rule. A clean robots.txt for a small business site typically looks like this:
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
Sitemap: https://yourdomain.com/sitemap.xml
Never use
Disallow: /on a live site. That single line blocks Googlebot from crawling your entire website.
This example allows Googlebot to crawl everything except your WordPress admin panel, which is the correct setup for most small business websites. After editing your robots.txt, use the robots.txt Tester in Google Search Console to confirm that the pages you want crawled are no longer blocked before you request reindexing.
Fix server errors and stray noindex tags
Server errors (5xx responses) mean your server failed to respond properly when Googlebot tried to visit the page. Contact your hosting provider if you’re seeing repeated 5xx errors, because the fix is almost always on the server side rather than in your content. For 404 errors on pages that should exist, check whether the URL changed after a recent site update and set up a 301 redirect from the old URL to the new one.
For noindex tags, open the page source by right-clicking and selecting "View Page Source," then search for the phrase noindex. If you find it inside a <meta name="robots"> tag on a page you want indexed, remove that tag in your website’s editor. WordPress users can check this setting directly inside the SEO settings for each page using their installed SEO plugin.
Step 5. Fix duplication, canonicals, and redirects
Duplicate content is one of the most common reasons pages end up in the Excluded section of the google search console coverage report, and it’s one of the easiest issues to miss until it compounds. When Google finds multiple URLs that serve nearly identical content, it picks one to index and pushes the rest into Excluded under labels like "Duplicate without user-selected canonical" or "Duplicate, Google chose different canonical than user." Fixing this requires you to take an explicit position on which version of each page is the authoritative one and then communicate that clearly through canonical tags and redirects.
Identify duplicate pages in the Excluded group
Open the Excluded section of the report and look for any reason that includes the word "duplicate." Click each reason to see the list of affected URLs, then compare those URLs against your intended site structure. Common duplication patterns include HTTP vs. HTTPS versions, trailing slash vs. no trailing slash, and parameter-based URLs generated by filters or session tracking (for example, /services/?ref=homepage and /services/ showing as separate pages).
If you see more than five duplicate URLs pointing to the same page, a technical issue is likely generating them automatically, and you need to find the source before individual fixes will hold.
Set the correct canonical tag
A canonical tag is an HTML element you place in the <head> section of a page to tell Google which URL is the definitive version. Here is what a correct canonical tag looks like:
<link rel="canonical" href="https://yourdomain.com/services/" />
Every page on your site should carry a self-referencing canonical tag that points to its own preferred URL. On duplicate pages, point the canonical to the primary version you want indexed. WordPress users can set canonical URLs directly inside their SEO plugin settings on each page without touching code.
Fix redirect chains and loops
A redirect chain happens when URL A redirects to URL B, which then redirects to URL C. Each additional hop slows Googlebot down and dilutes link signals, which pushes pages toward the Excluded group or causes Google to index an unintended intermediate URL. Audit your redirects by listing every 301 redirect your site uses and confirming that each one goes directly to the final destination URL with no intermediate stops.
| Redirect type | What it means | What to do |
|---|---|---|
| 301 chain (3+ hops) | Multiple intermediate redirects | Repoint directly to the final URL |
| 302 to important page | Temporary redirect treated as non-permanent | Change to 301 |
| Redirect loop | URL A redirects back to URL A or itself | Remove the conflicting rule in your server config |
After updating any canonical tags or redirect rules, re-inspect the affected URLs using the URL Inspection tool and request indexing on the pages you corrected.
Step 6. Handle low value pages and crawl budget
Not every page on your site deserves Google’s attention, and sending Googlebot to the wrong places wastes the crawl budget Google allocates to your site. Crawl budget is the number of pages Googlebot will crawl on your site within a given timeframe. When low-value pages consume that budget, your important pages get crawled less frequently, which slows down indexing and can keep fresh or updated content out of search results longer than necessary. The google search console coverage report helps you spot these pages before they become a real drain.
For most small business sites with under 500 pages, crawl budget is rarely a crisis, but thin pages and parameter URLs can still slow down how quickly Google processes your updates.
Identify which pages are draining your crawl budget
Start by opening the Excluded section of the Page indexing report and looking for URL patterns that repeat in large numbers. Parameter-based URLs, paginated archive pages, tag pages, and filtered product URLs are the most common culprits. Each of these adds a URL to Google’s crawl queue without adding unique, useful content for your visitors. Pull the list of excluded URLs, group them by pattern, and assess whether any of those patterns also appear in your Valid group, because that signals Google is still crawling and processing those pages.
Use this checklist to identify low-value page types worth addressing:
- Thin pages with fewer than 200 words of unique content
- Tag and category archive pages with only one or two posts
- Parameter URLs generated by session IDs, tracking codes, or sort filters
- Paginated pages beyond page two or three with minimal unique content
- Old campaign landing pages from previous promotions with no current purpose
How to remove low value pages from Google’s attention
Once you have identified the low-value pages, you have three practical options depending on the page type. Add a noindex tag to pages that should stay accessible to visitors but don’t need to appear in search results. Block parameter-based URLs using the URL Parameters tool or through your robots.txt file if they serve no SEO value. For pages with no remaining purpose, delete them and set up a 301 redirect to the most relevant active page on your site.
Here is a noindex tag template to place inside the <head> of any page you want to keep visible but pull out of Google’s index:
<meta name="robots" content="noindex, follow" />
Using follow keeps Googlebot following links on that page, which protects your internal link structure while removing the page from the index. After applying noindex tags, give Google two to four weeks to process the changes before checking the Excluded group again for confirmation.
Step 7. Validate fixes and keep it clean over time
After you apply a fix, your work isn’t done until you confirm that Google processed the change and updated its records for that page. Validating fixes closes the loop on each issue you resolved and gives you clear evidence that the google search console coverage report is moving in the right direction. Skipping this step means you’re operating on assumption rather than data, and small mistakes can quietly resurface without you knowing.
Request indexing and confirm the fix
Once you’ve corrected an issue on a specific URL, navigate to the URL Inspection tool, paste in the fixed URL, and click "Request Indexing." This signals to Google that the page is ready to be recrawled and re-evaluated. After submitting the request, wait 24 to 72 hours before checking back, since Google needs time to recrawl and process the updated page.
Requesting indexing does not guarantee immediate results, but it moves your page to the front of Google’s crawl queue and typically speeds up the update by several days compared to waiting passively.
Follow this validation checklist after fixing any error or exclusion:
- Apply the fix directly on the page or in the relevant configuration file
- Open the URL Inspection tool and paste in the corrected URL
- Click "Test Live URL" to confirm the live version renders and reads correctly
- Click "Request Indexing" once the live test passes
- Return in 48 to 72 hours and re-inspect the URL to confirm the status changed
- Check the Page indexing report to verify the error count in that category decreased
Build a monthly review routine
Keeping your index clean over time requires a consistent review schedule, not just reactive troubleshooting when something breaks. Set a recurring calendar reminder to open the Page indexing report on the same day each month. During each review, check whether the error count increased, the valid page count dropped, or new exclusion reasons appeared that weren’t there the previous month. Any of those three signals points to a change on your site that introduced a new problem.
A simple monthly tracking table helps you spot trends before they become serious issues:
| Month | Valid pages | Errors | Warnings | Excluded |
|---|---|---|---|---|
| Month 1 | (record count) | (record count) | (record count) | (record count) |
| Month 2 | (record count) | (record count) | (record count) | (record count) |
| Month 3 | (record count) | (record count) | (record count) | (record count) |
Tracking these numbers month over month gives you a baseline to measure against every time you update your site, add new pages, or change your technical configuration.
Next steps for a healthier index
The google search console coverage report gives you a direct line into how Google processes your site, and the steps in this guide give you everything you need to act on what you find. Work through errors first, then warnings, then the Excluded group. Fix the root cause, validate the change, and track your page counts month over month so small issues don’t quietly grow into larger problems that cost you traffic.
Your website’s search visibility depends on Google being able to crawl, process, and index the right pages without interruption. If you’ve worked through this guide and still have pages stuck in error or excluded, the problem often traces back to site structure or technical configuration that needs a closer look. Avatar Website Design builds and maintains small business websites with SEO health built in from the start, so your pages reach the customers who are already searching for what you offer.