

Your website might look great on the surface, but if search engines can’t crawl and index it properly, potential customers will never find you. That’s where technical SEO best practices come in, the behind-the-scenes work that makes your site visible, fast, and easy for Google to understand. For small businesses competing for local search visibility, ignoring this stuff is like opening a storefront with no sign on the door.
At Avatar Website Design, we build websites with these technical foundations baked in from day one. Every site we launch is structured for clean crawlability, optimized for speed, and built to perform across all devices. But whether you’re working with us or managing your own site, you need to understand what’s happening under the hood.
This guide breaks down 10 actionable technical SEO practices that directly impact how search engines discover, crawl, and rank your pages. We’re covering everything from site architecture and XML sitemaps to page speed optimization and structured data. No fluff, just the specific steps you can audit and implement to strengthen your website’s technical foundation and start showing up where your customers are searching.
1. Get a Technical SEO Audit and a Fix List
Before you can fix anything, you need to know what’s broken. A technical SEO audit gives you a complete picture of your site’s health, from crawl errors and broken links to missing metadata and slow page loads. Without one, you’re guessing, and guessing wastes your limited time and budget.
What it improves and why it matters
Running an audit directly improves your site’s crawlability, indexation, and search ranking potential. Search engines like Google send bots to discover and evaluate your pages, and any technical barrier, whether it’s a broken redirect, a missing sitemap, or a slow server, can prevent those bots from properly indexing your content. Fixing audit findings is the foundation of every solid set of technical SEO best practices.
A technical audit is not a one-time task. Sites change with every update, plugin installation, or content addition, and new issues appear right along with those changes.
What to check first
Start with Google Search Console, which is free and pulls real crawl data directly from Google. Look at the Coverage report to find pages Google can’t index, the Core Web Vitals report for speed issues, and the Sitemaps section to confirm your sitemap is submitted and error-free. These three areas will surface the most common and highest-impact problems on most small business websites.
After Search Console, run a dedicated site crawl to catch issues that Google hasn’t flagged yet, such as broken internal links, duplicate title tags, and pages with missing meta descriptions.
How to prioritize fixes with limited time
Not every audit finding deserves equal attention. Focus first on issues that block crawling or indexation entirely, such as pages accidentally blocked by robots.txt or critical pages returning 404 errors. Second, tackle issues that directly affect ranking signals, like duplicate content, missing canonical tags, and slow page speed. Save cosmetic or low-traffic page issues for last.
Common mistakes to avoid
Many site owners run an audit once and then ignore the results. Another frequent mistake is fixing low-priority issues first simply because they appear at the top of a report. Always sort findings by severity and estimated traffic impact, and focus on the fixes that will move the needle for your core pages before addressing edge cases.
2. Build a Crawl-Friendly Site Structure
A well-organized site structure helps search engine bots navigate your site efficiently and understand how your pages relate to each other. When your structure is logical and shallow, crawlers can reach every important page quickly, which directly supports stronger indexation and ranking potential.
What it improves and why it matters
Your site’s structure controls how crawl budget gets distributed across your pages. If your hierarchy is too deep or disorganized, Google’s bots may never reach lower-level pages, leaving valuable content unindexed. Site structure is one of the technical SEO best practices that has the most direct effect on how efficiently crawlers index your content.
The deeper a page is buried in your site hierarchy, the less authority it typically receives and the less likely Google is to crawl it regularly.
What to check first
Open your site and manually count how many clicks it takes to reach your most important service or product pages from the homepage. Anything beyond three levels is a warning sign. You can also use Google Search Console’s Coverage report to identify pages that aren’t being indexed, which often signals a structural problem.
How to fix it on most small business sites
Reorganize your navigation menu and page hierarchy so your core service pages are directly accessible from the top-level menu. Group related pages under clear category pages and make sure every page links naturally back up to a parent or related page.
Common mistakes to avoid
Avoid creating deep subdirectory structures just to organize content by date or category when it isn’t necessary. Many small business sites also make the mistake of burying their most profitable service pages three or four levels deep, effectively hiding them from both users and crawlers.
3. Strengthen Internal Linking and Remove Orphan Pages
Internal linking does more than help users navigate your site. It tells search engines which pages matter most and how your content connects. When crawlers follow internal links to discover and re-visit pages, your linking structure directly controls how effectively your site gets indexed.
What it improves and why it matters
Strong internal linking distributes page authority across your site, which helps lower-level pages rank better on their own. An orphan page, meaning a page with no internal links pointing to it, is practically invisible to search engine crawlers. Fixing orphan pages is one of the most overlooked technical SEO best practices for small business sites.
If a page on your site has no internal links pointing to it, search engines may never discover or index it, regardless of how good the content is.
What to check first
Start by running a site crawl using Google Search Console’s Coverage report to identify pages that aren’t getting indexed. Cross-reference that list against your navigation menus and page content to find pages that exist in isolation with no links pointing to them.
How to fix it with a simple linking plan
Create a simple spreadsheet listing your core service and location pages, then identify at least two other pages on your site that can naturally link to each one. Add contextual links within your body content, not just your navigation, so crawlers encounter them during a standard page crawl.
Common mistakes to avoid
Avoid linking every page to every other page just to close gaps. Irrelevant or forced links confuse both users and crawlers. Also, don’t rely solely on your navigation menu to carry all your internal links.
4. Create and Submit a Clean XML Sitemap
An XML sitemap is a file that lists every URL on your site you want search engines to index, giving crawlers a direct roadmap to your content. Without one, Google still discovers most pages, but a well-maintained sitemap speeds up discovery and indexation when it matters most, especially for new or low-link pages.
What it improves and why it matters
A clean sitemap reduces the guesswork for search engine bots by telling them exactly which pages to prioritize. This is a core part of technical SEO best practices because it directly supports faster indexation and keeps your crawl budget focused on pages that actually matter to your business.
A bloated or error-filled sitemap is worse than no sitemap at all because it wastes crawl budget on pages that shouldn’t be indexed.
What to check first
Open Google Search Console and navigate to the Sitemaps report to confirm your sitemap is submitted, review how many URLs it contains, and check whether Google flagged any errors. Compare that submitted URL count against your actual page count to spot major discrepancies quickly.
How to fix sitemap bloat and errors
Remove URLs that return non-200 status codes, pages tagged with noindex, and any low-value or duplicate URLs from your sitemap. Your sitemap should only list canonical, indexable pages that you genuinely want Google to discover and rank.
Common mistakes to avoid
Don’t submit a sitemap once and forget it. Any time you add or remove pages, your sitemap should update automatically through your CMS. Also, avoid including paginated or filtered URLs unless those pages carry genuinely unique, rankable content.
5. Control Crawling with robots.txt and Meta Robots
Your robots.txt file and meta robots tags give you direct control over what search engine bots can and cannot crawl on your site. Used correctly, they help you focus crawl budget where it matters and keep low-value pages out of Google’s index.
What it improves and why it matters
These two tools improve your site’s crawl efficiency by preventing bots from wasting time on pages that don’t contribute to your search rankings, such as admin panels, duplicate filtered URLs, or internal search results. Keeping crawlers focused on your valuable pages is a core part of technical SEO best practices, and mismanaging these controls can quietly suppress your entire site’s visibility.
Blocking the wrong pages in robots.txt is one of the fastest ways to accidentally hide your site from Google, with no error messages to warn you.
What to check first
Visit your robots.txt file directly by typing your domain followed by /robots.txt in your browser. Confirm it isn’t blocking pages you need Google to crawl and index. You should also review your CMS settings to check whether any meta robots tags are set to noindex on pages you want ranked.
How to block the right pages without hurting SEO
Use robots.txt to block crawling of areas like staging environments, duplicate parameter URLs, and back-end admin directories. Use meta robots noindex tags for pages you want crawlers to reach but not include in search results, such as thank-you confirmation pages.
Common mistakes to avoid
Never block a page in robots.txt and also apply a noindex tag to it. Google can’t read the noindex tag if crawling is blocked, so the page may still appear in search results without content. Also avoid using broad disallow rules that block entire directories when you only need to exclude specific URLs.
6. Consolidate URL Versions and HTTPS
Your site can load from multiple URL versions at once, such as with and without "www," or over HTTP and HTTPS. To search engines, each version is a separate address, which splits your ranking signals and confuses crawlers about which one to index. Pulling everything under a single canonical URL format is one of the most impactful technical SEO best practices you can apply to your site.
What it improves and why it matters
URL consolidation focuses your link equity and crawl signals on one address rather than diluting them across duplicates. Google also confirmed HTTPS as a ranking signal, and unresolved mixed content between HTTP and HTTPS actively triggers browser security warnings that erode visitor trust.
Duplicate URL versions silently drain the authority your pages have built, often without a single error appearing in Search Console.
What to check first
Type the four main domain versions into your browser, with and without "www" over both HTTP and HTTPS, and confirm they all 301 redirect to your preferred version. Also inspect your HTTPS pages for mixed content warnings by checking your browser’s security indicator on several pages across your site.
How to standardize domains, slashes, and parameters
Choose one URL format, then configure 301 redirects from every other version to it. Decide whether your URLs include trailing slashes and apply that rule consistently across every page. Address URL parameters that generate duplicate pages by either redirecting them to the clean version or assigning canonical tags.
Common mistakes to avoid
Avoid building multi-hop redirect chains, such as HTTP redirecting to HTTPS and then non-www redirecting to www as a second hop. Each extra step wastes crawl budget. Never leave mixed content unresolved either, where a page loads over HTTPS but still pulls in images or scripts over HTTP.
7. Fix Indexation Signals with Canonicals and Noindex
Duplicate content and thin pages create confusion for search engines about which version of a URL to rank. Using canonical tags and noindex directives correctly sends clear signals that tell Google exactly which pages to index and which to ignore, which keeps your indexation clean and your ranking signals consolidated.
What it improves and why it matters
Getting your indexation signals right directly improves how much authority flows to your most important pages. When Google encounters multiple versions of the same content without a canonical tag, it guesses which version to rank, and it often guesses wrong. This is one of the most impactful technical SEO best practices you can apply to sites that have grown organically over time.
Leaving duplicate or thin pages unaddressed doesn’t just waste crawl budget; it actively dilutes the ranking potential of your strongest content.
What to check first
Open Google Search Console and review the Coverage report for "Duplicate without user-selected canonical" and "Duplicate, Google chose different canonical than user" errors. Both signals tell you Google is encountering pages it can’t confidently distinguish from each other, which requires your immediate attention.
How to handle duplicates and thin pages correctly
Add a self-referencing canonical tag to every indexable page and point duplicate or near-duplicate variations back to the primary URL. For genuinely thin pages with no ranking value, apply a noindex meta tag rather than deleting them if the page still serves a functional purpose for users.
Common mistakes to avoid
Never apply both a canonical tag pointing to another page and a noindex tag on the same page. These signals conflict and confuse crawlers. Also avoid canonicalizing paginated pages back to page one, as this tells Google to ignore all content that appears only on those deeper pages.
8. Improve Core Web Vitals and Page Speed
Page speed is no longer just a user experience concern. Google uses Core Web Vitals as direct ranking signals, measuring how fast your pages load, how quickly they respond to user input, and how stable your layout is during loading. Slow pages lose both rankings and visitors.
What it improves and why it matters
Improving your Core Web Vitals directly affects your search ranking position and your bounce rate. Google’s three primary metrics are Largest Contentful Paint (LCP), Interaction to Next Paint (INP), and Cumulative Layout Shift (CLS). These metrics are among the most measurable technical SEO best practices because they directly reflect real user experience on your site.
A one-second delay in page load time can reduce conversions by up to 7%, which means slow pages cost you both rankings and revenue.
What to check first
Run your pages through Google PageSpeed Insights and review your Core Web Vitals report in Google Search Console under the Experience section. Both tools show you which pages fail the LCP, INP, or CLS thresholds and provide specific recommendations tied to each failing metric.
How to get faster loads with high-impact changes
Start by compressing and properly sizing images, since oversized image files are the single most common cause of poor LCP scores on small business sites. Also enable browser caching, use a content delivery network, and ensure your hosting server response time stays under 200 milliseconds.
Common mistakes to avoid
Avoid chasing a perfect PageSpeed score by optimizing metrics that don’t affect your real-user field data. Also, don’t defer fixing layout shift issues because they seem minor. Unstable layouts frustrate users and directly drag down your CLS score, which Google weights heavily in its page experience assessment.
9. Reduce JavaScript and Rendering Issues
Modern websites rely heavily on JavaScript to display content dynamically, but that creates a real problem for search engines. When critical content only appears after JavaScript executes, Google’s crawler may never see it during initial discovery, leaving your pages looking empty to the systems that decide whether to rank them.
What it improves and why it matters
Reducing your reliance on JavaScript for delivering core content improves crawl reliability and indexation speed significantly. Googlebot does process JavaScript, but it queues that rendering separately from its initial crawl, which means there’s a delay between when your page is discovered and when its full content gets evaluated. This is one of the more technical technical SEO best practices, but its impact on indexation is direct and measurable.
If your homepage headline or service descriptions only load after JavaScript runs, Google may index a blank or incomplete version of your page.
What to check first
Open your pages with JavaScript disabled in your browser to see what content remains visible. You can also use Google Search Console’s URL Inspection tool to view the rendered version of any page as Google sees it, which reveals gaps between your raw HTML and what actually appears after JavaScript executes.
How to make key content render reliably for crawlers
Move your primary headings, body text, and internal links into your raw HTML so they’re immediately available without JavaScript. Use server-side rendering or static generation for your core pages wherever your platform supports it.
Common mistakes to avoid
Avoid loading navigation menus or service descriptions exclusively through JavaScript frameworks. Also, don’t assume Google renders every page immediately; delayed rendering means recently updated content can take days longer to get re-indexed.
10. Clean Up Broken Pages, Redirects, and Status Codes
Every broken link, dead page, and redirect chain on your site wastes crawl budget and signals to Google that your site isn’t well-maintained. These issues compound quietly over time, especially on sites that have gone through redesigns or content migrations.
What it improves and why it matters
Cleaning up status code issues directly improves crawl efficiency and user experience, which are both factors Google weighs in its ranking decisions. When bots hit 404 errors or follow long redirect chains, they burn through your crawl budget before reaching your most important pages. Fixing these is a foundational step in any solid set of technical SEO best practices.
A redirect chain with three or more hops passes significantly less link authority than a single clean 301 redirect to the final destination.
What to check first
Use Google Search Console’s Coverage report to identify pages returning 404 errors, redirect issues, and pages flagged as soft 404s. Soft 404s are pages that return a 200 status code but serve no real content, which tricks crawlers into wasting index space on empty or near-empty pages.
How to fix 404s, redirect chains, and soft 404s
Update any internal links pointing to 404 pages so they go directly to the live destination. Collapse redirect chains into single 301 redirects from the original URL to the final one. For soft 404s, either build out the page with real content or apply a proper noindex tag.
Common mistakes to avoid
Avoid leaving orphaned 301 redirects in place from URLs that no longer receive internal or external links. Also, never point multiple redirect chains at each other in a loop, as this makes pages permanently inaccessible to both users and crawlers.
Taking Action: Implementing Your Technical SEO Plan
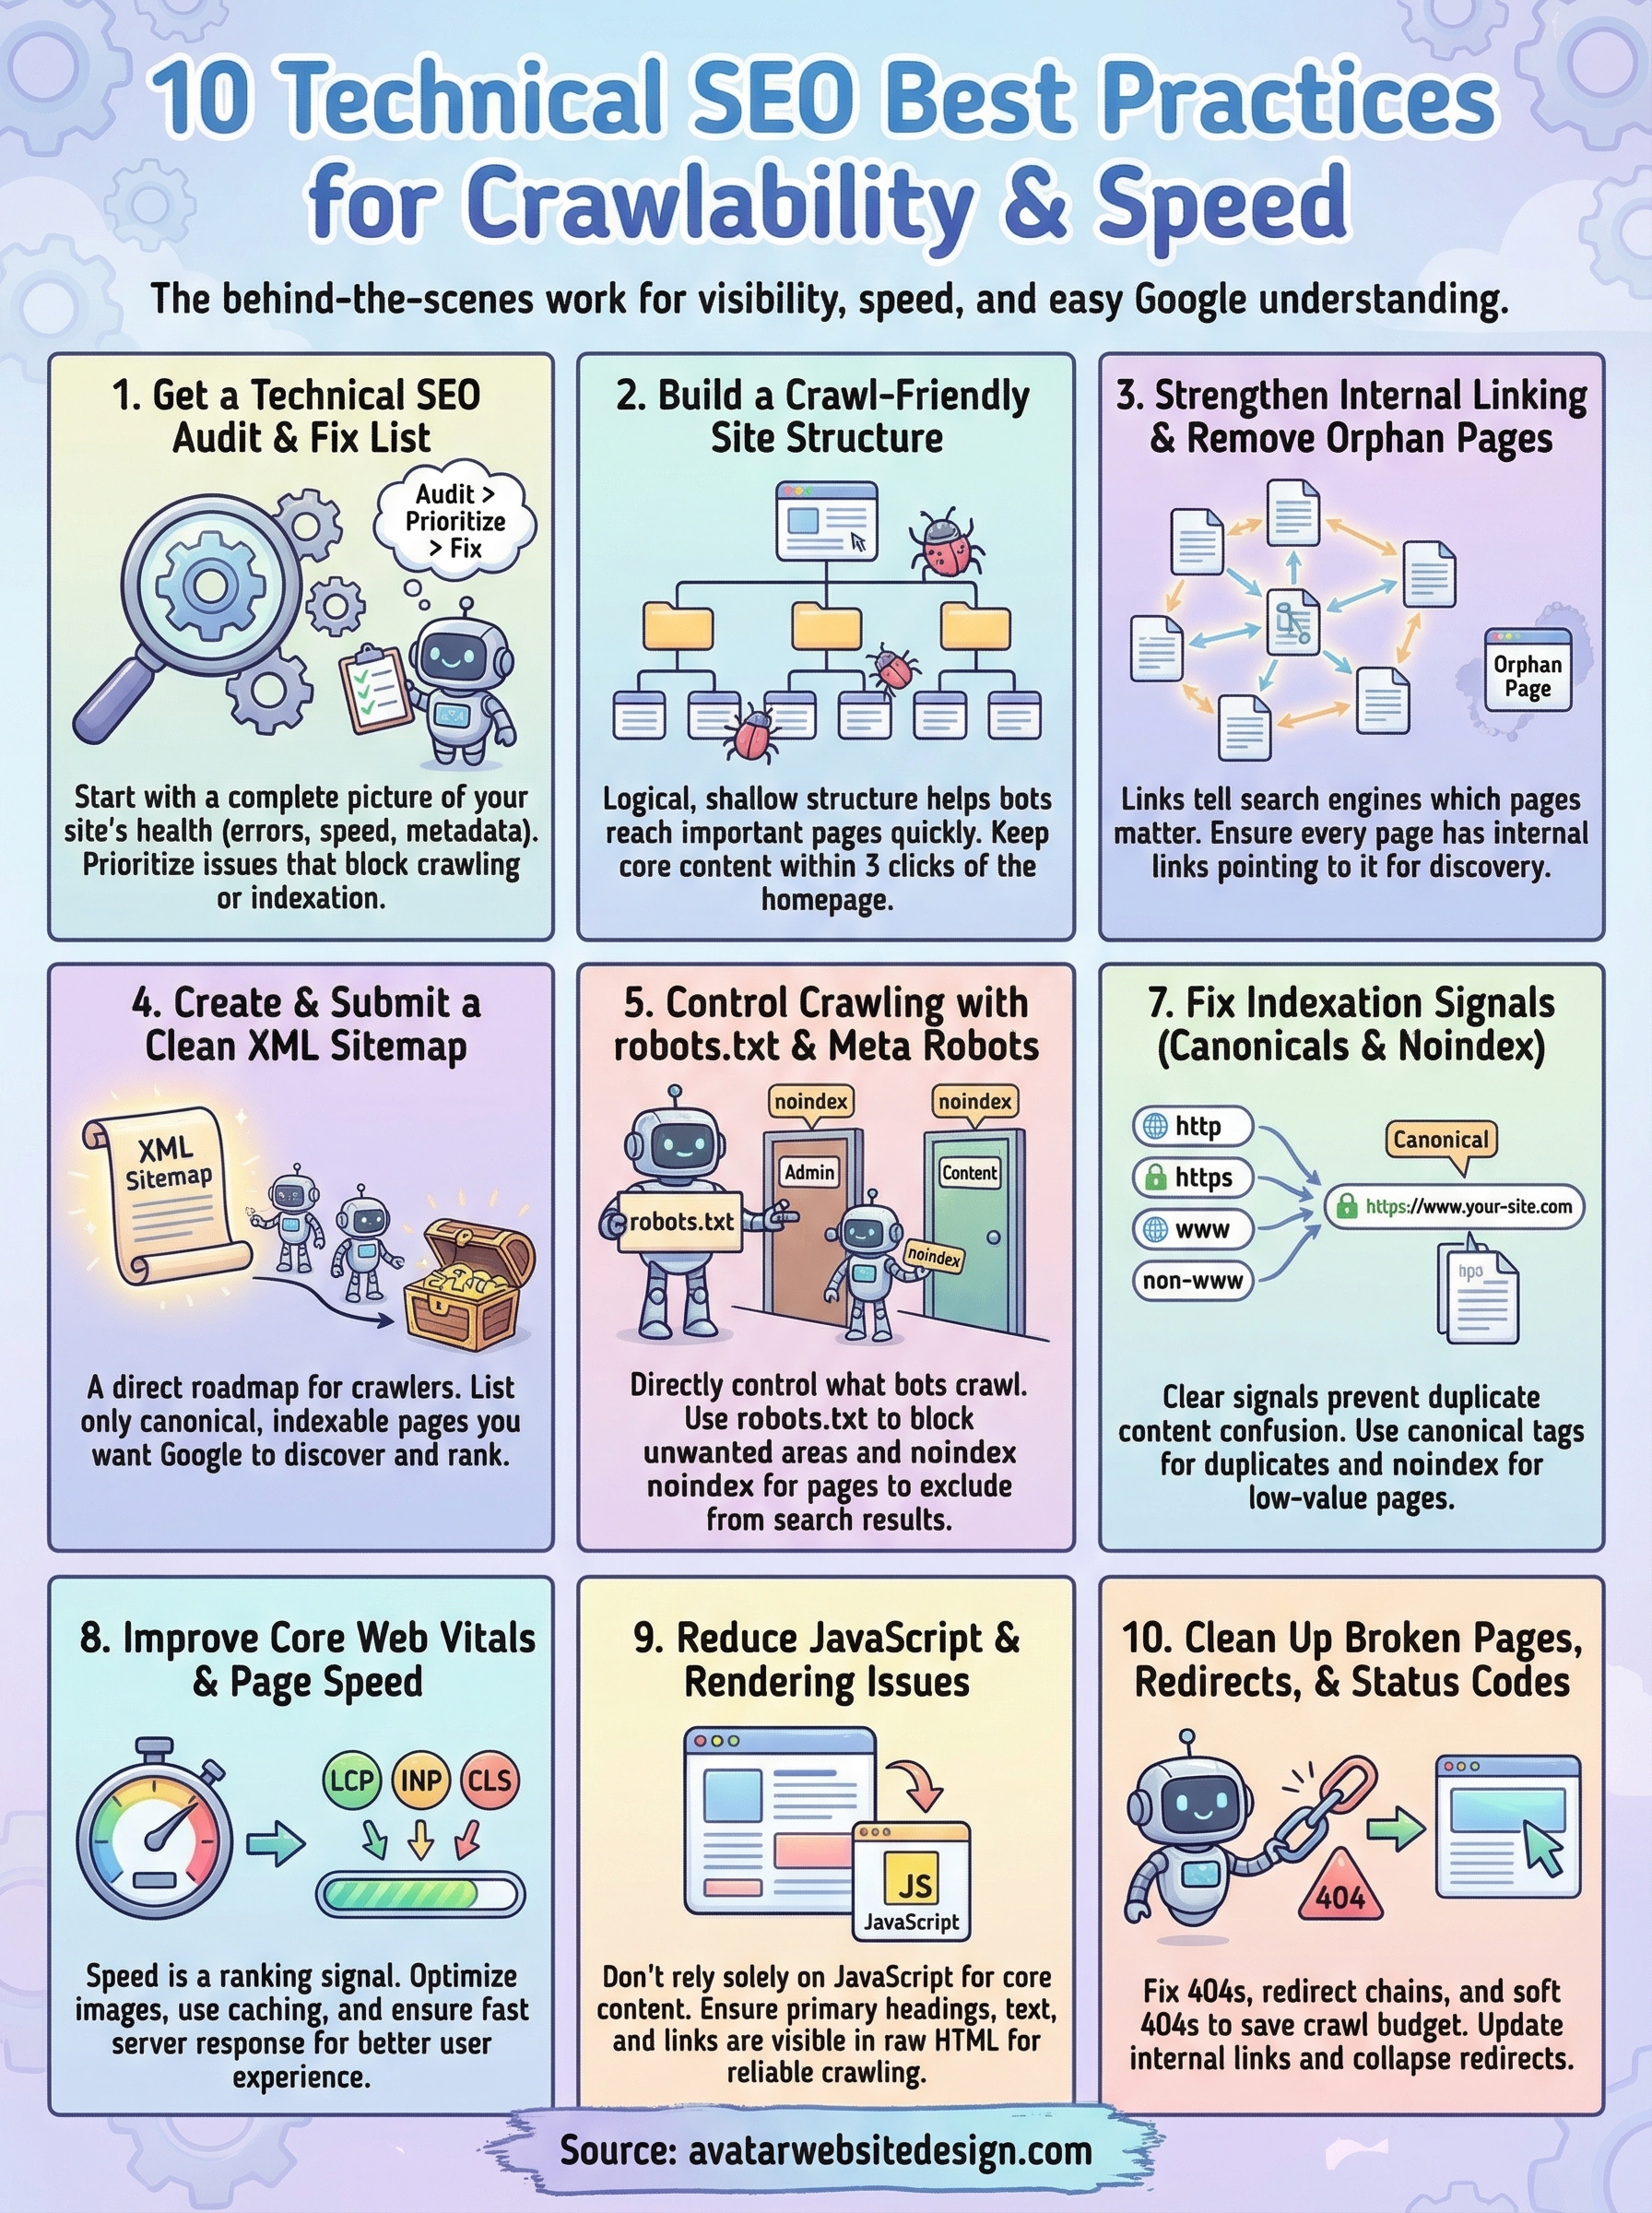
You now have a complete set of technical SEO best practices to audit, prioritize, and act on. Each practice in this list targets a specific part of how search engines discover, crawl, and rank your pages. Start with an audit in Google Search Console, fix the issues that block indexation first, and work your way through the rest systematically. Small, consistent improvements add up faster than you’d expect when you address the right problems in the right order.
If managing all of this yourself sounds like too much on top of running your business, you don’t have to figure it out alone. At Avatar Website Design, we build every website with these technical foundations already in place, so you launch with clean structure, fast load times, and proper indexation signals from day one. If you’re ready to get a site that performs as well as it looks, talk to the Avatar Website Design team today.